Incrementality Testing: A Practical Guide for Marketers
09/16/2026
Marketing Services
A practical guide to incrementality testing — test design, sizing rules, common pitfalls, tools, and how to turn lift results into budget decisions.
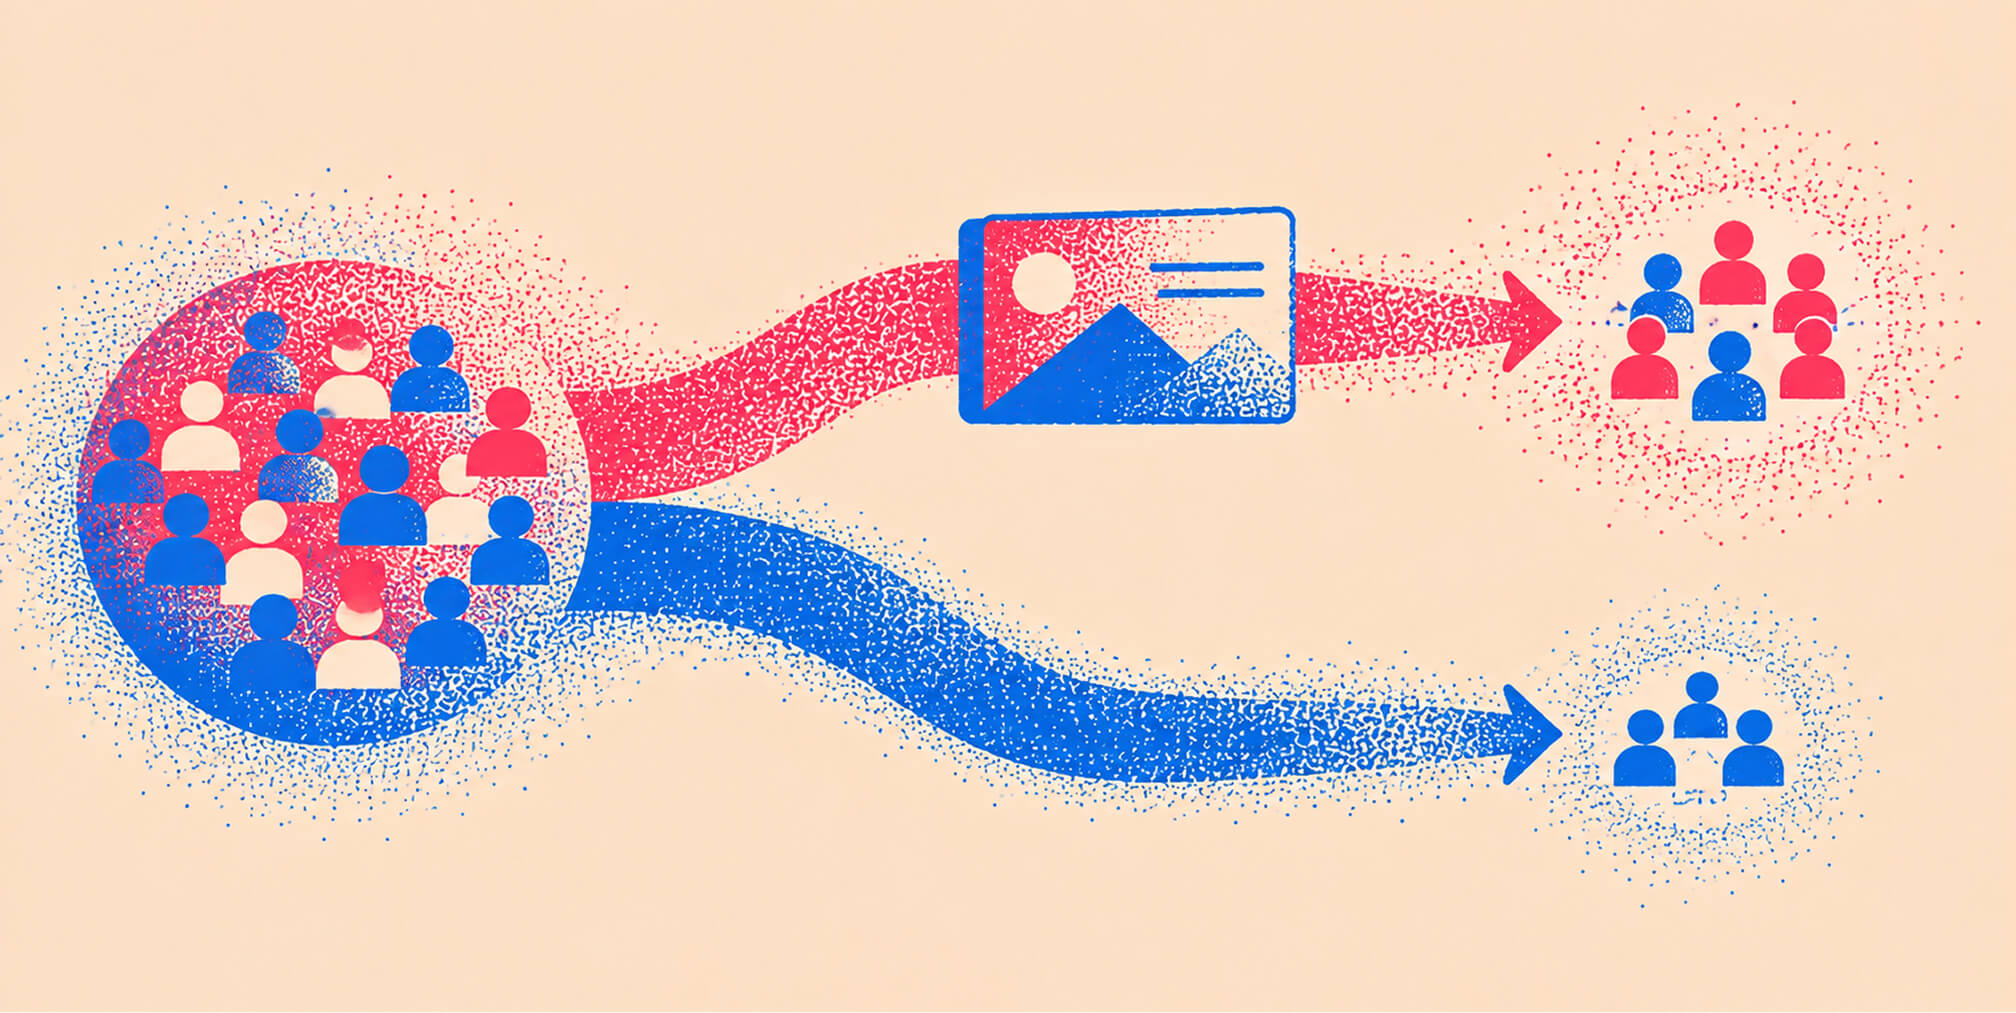
Incrementality testing is a randomized controlled experiment that isolates causal lift by comparing a group exposed to your advertising against a holdout group that sees no ads. The result tells you exactly how many conversions your campaign actually caused, not just correlated with. If you're deciding whether to cut branded search spend, scale a new upper-funnel channel, or validate whether retargeting is pulling its weight, this is the method that gives you a defensible answer.


How Incrementality Testing Measures Causal Lift, and Choosing the Right Test Design
Before you run one, check three things:
- A decision-owner exists who will act on the result, whether that's reallocating budget or killing a channel.
- Your conversion volume is sufficient. A low number of total conversions is generally not enough for a reliable platform lift test.
- The treatment is isolatable. You're testing one variable at a time, whether that's a channel, a creative, or a targeting strategy.
If all three are true, you're ready to design a test worth running.
How does incrementality testing actually measure causal lift?
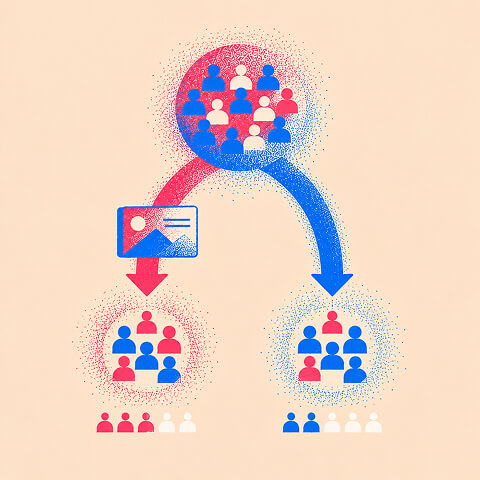
The logic is clean: split your audience randomly into two groups, show ads to one and suppress them for the other, then compare conversion rates at the end of the window. The difference between those rates is your causal lift. Not a modeled estimate. Not a correlated signal. A measured gap.
Here's the flow in practice:
- Audience pool is defined (users, geos, or accounts).
- Random assignment splits the pool into exposed (treatment) and holdout (control).
- Treatment group sees your ads; holdout is suppressed or shown a PSA.
- Measurement window closes; conversions are counted in each group.
- Lift is computed from the difference.
The three core formulas every practitioner needs:
- Incremental conversions = Conversions (exposed) minus Conversions (holdout, scaled to same size)
- Incremental conversion rate (iCVR) = Conversion rate (exposed) minus Conversion rate (holdout)
- Incremental ROAS = Incremental revenue ÷ Ad spend on the exposed group
Randomization methods vary by context. User-level holdouts, run either through a platform's native tool or server-side, work well for high-volume digital channels where individual identity is trackable. Geo-split tests assign entire markets to treatment or control, which makes them useful when you can't suppress ads at the user level or when you're measuring offline sales. PSA or ghost-bidding approaches serve as the holdout mechanism when you need to suppress spend without alerting the platform's algorithm. A/B testing and incrementality serve different jobs: A/B tests compare variants inside a campaign, while incrementality testing asks whether the campaign itself caused conversions beyond organic demand.
Which test design fits your constraints?
Three dominant designs cover most scenarios: user-level holdouts, geo-split (market) lift tests, and platform-native conversion lift studies. Each maps to different constraints.
| Design | Best For | Required Sample / Conversions | Typical Duration | Data Complexity | Privacy Constraints |
|---|---|---|---|---|---|
| User-level holdout | High-volume digital channels (paid social, display) | 600+ total conversions per group | 2-4 weeks | Medium: needs identity stitching and deduplication | Must respect opt-outs; platform policies govern suppression |
| Geo-split (market) lift | Cross-channel, offline sales, or channels where user suppression isn't possible | Matched markets with comparable baseline rates | 4-8 weeks | High: requires matched-market selection and external data validation | Lower identity dependency; geo-level aggregation is privacy-safe |
| Platform-native conversion lift | Quick directional checks; early-stage channel validation | Platform-defined minimums (varies by platform) | 1-3 weeks | Low: platform manages randomization | Platform controls data; limited raw export |
For high-volume digital channels, user-level holdouts give you the most control. For cross-channel or offline measurement, a geo holdout test is the right call. Platform-native studies are useful for directional signals, but they tend to report higher lift than independent third-party or geo-validated studies, so treat them as one input, not the final word.
Pro Tip: When designing a geo-split test, match your treatment and control markets on baseline conversion rate, population size, and seasonal patterns before the test launches. A poorly matched control market can absorb organic lift and make a real effect invisible.
Free Brand Health Audit
Make sure your brand is built to sell
Search has changed. Your customers aren't just Googling anymore. They're asking ChatGPT, Perplexity, Gemini and other AI platforms what to buy, who to trust and which brands they should consider.
If your brand isn't showing up clearly in those answers, you're already losing opportunities. Our free Brand Health Audit shows you where your brand stands across traditional search, AI search and brand positioning.

Sample brand audit
Live preview
Traditional search
72
AI search (GEO)
34
Brand positioning
58
How It Differs From A/B Testing, Attribution, and MMM, Plus How to Run a Test
How does incrementality testing differ from A/B testing, attribution, and MMM?
Each method answers a different question. Confusing them is one of the most expensive mistakes in measurement.
Incrementality testing measures causation. Attribution and A/B testing answer different tactical questions. MMM provides portfolio-level correlational allocation. Here's how they split:
A/B testing compares variants inside a campaign, such as two ad creatives or two landing pages. The randomization unit is typically the user or session, and the question is "which version performs better?" It doesn't tell you whether the campaign itself is driving incremental demand.
Attribution reports which touchpoints were present before a conversion. It's useful for daily optimization and understanding the observed path to purchase. The problem is that it overclaims: a user who would have converted anyway still gets a touchpoint credited. Attribution explains observed paths; incrementality testing proves whether those paths caused anything. Trust attribution for execution-level tuning; validate it with experiments for budget decisions.
Marketing Mix Modeling (MMM) gives you an always-on, portfolio-level view of channel contribution over time. It's correlational and valuable for strategic allocation, but it needs calibration. That's where incrementality tests come in: run a test, measure true causal lift, and use that coefficient to recalibrate your MMM.
The operational sequence that works: use MMM to identify which channels are candidates for scrutiny, run an incrementality test to get causal proof on the top candidates, and use attribution for day-to-day campaign management between tests.
How to run an incrementality test from start to finish
Name the decision the test will drive before you touch any settings. What budget action will you take if lift is positive? What will you do if the result is null? Writing those answers down before the test launches is what separates a useful experiment from an expensive data exercise.
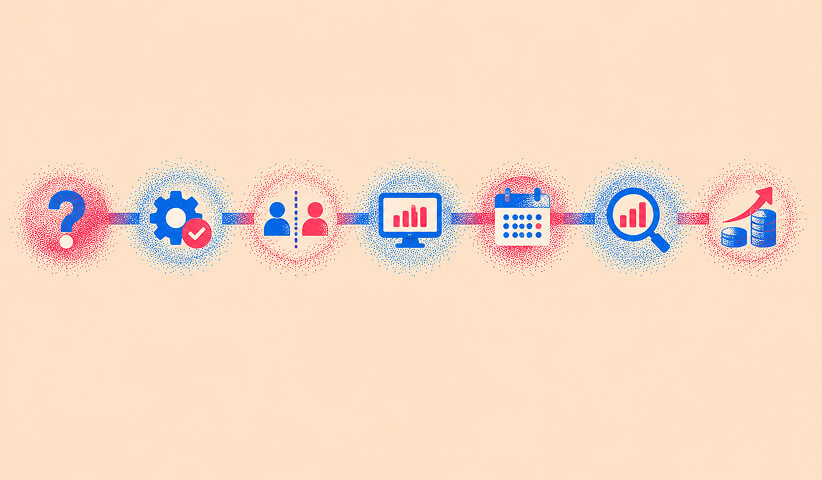
- Define the business question and KPI. "Does our retargeting campaign drive incremental purchases, or are we paying to convert people who would have bought anyway?" Pick one primary KPI: purchases, leads, or a proxy outcome.
- Compute feasibility. Use the sizing rule: conversions needed per group scale with 1 divided by lift². Detecting a 10% lift requires roughly 100x more conversions than detecting a 100% lift. If your expected volume is below 600 total conversions, reconsider the design or use a geo test.
- Choose your test design and holdout size. A 10-20% holdout is typical for user-level tests. Larger holdouts increase statistical power but raise opportunity cost.
- Instrument and validate data. Confirm your conversion events fire correctly, deduplication rules are set, and your tracking plan covers both groups before the test starts.
- Run the test for the full pre-specified window. Don't stop early. Checking significance mid-test and stopping when you first hit a threshold inflates false positives.
- Analyze results with pre-committed decision rules. Compute lift, confidence intervals, and incremental ROAS against the thresholds you set in step one.
- Report and act. Lift plus CI, expected revenue impact, and a specific budget recommendation. Not a summary of what happened. A decision.
For integrated digital marketing strategy, incrementality tests fit into a quarterly rotation: one channel per quarter, results fed back into MMM.
Pro Tip: Write your analysis plan and decision rules before the test launches. Pre-registration prevents post-hoc rationalization and protects you from the temptation to reframe a null result as "directionally positive."
Timeline expectations vary sharply. A high-volume e-commerce brand can run a user-level test in two to three weeks. A B2B firm with a 60-day sales cycle needs a window that encompasses a full conversion cycle, often 8-12 weeks minimum, or the test will undercount conversions in the exposed group and produce a misleading null.
Is your attribution data quietly overclaiming? Keep reading!
If you need causal proof instead of correlation before your next budget call, contact us for a free custom quote.
Common Pitfalls, and the Tools and Data Architecture You Need
What are the most common pitfalls in incrementality testing?
The most dangerous wrong inference is reading an underpowered null result as proof that your ads have no effect. A null result is an upper bound on lift, not evidence of zero. If your test lacked the power to detect a 15% lift, you haven't proven the lift doesn't exist.
- Underpowered tests: Running a test with too few conversions produces wide confidence intervals that can't rule out meaningful effects. Fix: run the feasibility calculation before committing.
- Contamination between test and control: In geo tests, if a control market is adjacent to a treatment market and consumers cross borders (physically or digitally), the control absorbs some treatment effect. Fix: choose geographically isolated markets and monitor for spillover.
- Early stopping: Peeking at results and stopping when significance is first reached inflates false positives. Fix: run to the pre-specified window, no exceptions.
- Platform-report bias: Platform-native lift studies tend to overstate lift relative to independent validation. Fix: use platform results as directional signals, not final proof.
- Mis-specified KPIs: Testing on clicks or impressions when the business decision is about revenue produces results that don't translate to budget actions. Fix: test on the KPI that drives the actual decision.
- Conversion deduplication errors: If the same conversion is counted in both groups due to a tracking error, lift estimates are corrupted. Fix: validate deduplication logic before launch.
One-sentence privacy note: suppressing ads for holdout groups and using user-level identifiers must respect opt-outs, platform data policies, and applicable privacy regulations; loop in your legal and privacy stakeholders before the test design is finalized.
What tools and data architecture do you need for reliable measurement?
The right tool depends on your control over identity, conversion deduplication, and the unit of randomization you need. A platform-native lift study is fast and low-effort but gives you limited control and limited raw data access. A server-side or warehouse-native approach gives you full control but requires engineering investment.
Vendor selection checklist:
- Does the tool let you control randomization, or does the platform own it?
- Can you export raw event-level data for independent validation?
- Does it deduplicate conversions across channels and devices?
- Is the identity graph privacy-compliant and auditable?
- Can you define your own holdout percentage?
| Data Requirement | Specification |
|---|---|
| Required events | Impression or ad-served event + conversion event with shared user identifier |
| Deduplication rule | Last-touch or any-touch within the measurement window; define before launch |
| Lookback window | Match to your typical conversion lag (e.g., 7-day, 30-day) |
| Data latency | Under one day for daily monitoring; real-time for server-side validation |
Engineering fundamentals matter more than tool choice. Your tracking plan needs unique, stable identifiers for both exposed and holdout users. Server-side events or Conversions API (CAPI) integrations reduce browser-side signal loss, which is increasingly significant as third-party cookies disappear. Validate treatment assignment by confirming that holdout users received zero impressions from the tested channel during the window. For B2B websites with conversion tracking gaps, fixing instrumentation before running a test is non-negotiable.
Reading Lift Results, Real-World Examples, B2B Guidance, and Key Takeaways
How do you read lift results and turn them into budget decisions?
Report lifts with confidence intervals and pre-defined decision rules. A point estimate alone is misleading because it carries no information about uncertainty.
Here's a worked example:
- Exposed group: 10,000 users, 500 conversions (5.0% CVR)
- Holdout group: 10,000 users, 380 conversions (3.8% CVR)
- Incremental CVR: 5.0% minus 3.8% = 1.2 percentage points
- Incremental conversions: 120
- Average order value: $150
- Incremental revenue: $18,000
- Ad spend on exposed group: $9,000
- Incremental ROAS: $18,000 ÷ $9,000 = 2.0x
Now apply decision rules:
- If incremental ROAS exceeds your target threshold, scale the channel.
- If the confidence interval overlaps zero or goes negative, don't cut yet. Run a longer or larger test before making a budget decision.
- If the result is null but the test was underpowered, report the upper bound: "We can rule out a lift greater than X%, but we cannot confirm zero effect." Then redesign with more volume or a geo approach.
The analytics-driven measurement approach that produces real budget decisions always pairs a lift estimate with its confidence interval and a pre-committed action. A result without a decision rule attached is just a number.
Real-world examples: what incrementality testing looks like in practice
One of the most cited outcomes in the incrementality literature involves retargeting. A brand running retargeting at scale runs a holdout test and discovers that a significant portion of users in the "retargeted" group would have converted organically. The test reveals that a large portion of retargeting spend was being credited for conversions it didn't cause. The team reallocates that budget to prospecting, where the incremental lift is measurable and real. The outcome: the same or better revenue at lower cost.
Here's a mini worked example you can adapt:
- Business question: Does our branded paid search campaign drive incremental conversions, or are we paying for clicks from users who would have found us organically?
- Test design: User-level holdout, 15% holdout size, 4-week window
- Exposed group: 8,500 users, 425 conversions
- Holdout group: 1,500 users, 66 conversions (scaled to 8,500: ~374 expected)
- Incremental conversions: 425 minus 374 = 51
- Incremental CVR: ~0.6 percentage points
- Incremental revenue at $200 AOV: ~$10,200
- Spend on exposed group: $12,000
- Incremental ROAS: 0.85x
The decision rule was pre-set: if incremental ROAS falls below 1.0x, reduce branded search spend by 30% and redirect to upper-funnel channels. The test delivered a clear answer. Practical use cases like this, validating branded search, testing retargeting, proving new channel contribution, are exactly where incrementality analysis pays for itself.
What to report to stakeholders: lift percentage, confidence interval, incremental revenue impact, and a specific budget recommendation tied to the pre-committed decision rule.
When incrementality testing is hard: B2B, low-volume, and long-cycle guidance
Low-volume and long-sales-cycle contexts require different designs or different priorities. A B2B SaaS firm closing 30 deals a month cannot run a statistically valid user-level lift test on a two-week window. The math simply doesn't work.
Practical options when volume is the constraint:
- Increase holdout size to boost statistical power, accepting higher opportunity cost.
- Extend the test window to encompass a full conversion cycle, including the typical sales lag.
- Switch to a geo test, which aggregates conversions at the market level and can reach significance faster in low-volume environments.
- Use proxy outcomes such as qualified leads, demo requests, or pipeline value when closed revenue is too sparse to measure directly. Pre-specify how the proxy maps to final revenue before the test starts.
- Triangulate with MMM when even geo tests are underpowered. Use MMM coefficients as a prior, run a smaller test to directionally validate, and update the model.
For SaaS email marketing and retention programs, the same principle applies: test on engagement or trial activation as a leading indicator when subscription revenue has too long a lag.
Pro Tip: For long sales cycles, define your leading indicator and its relationship to final revenue before the test launches. "Demo requests" is only a valid proxy if you know your demo-to-close rate and can apply it consistently. Pre-specifying that conversion keeps the analysis honest.
Power analysis for low-volume scenarios follows the same 1/lift² rule: if you expect a 20% lift and need 600 conversions per group, a 10% lift requires roughly 2,400 per group. When those numbers are out of reach, geo designs or longer windows are the practical path forward, not smaller tests that can't detect real effects.
Key Takeaways
Incrementality testing gives you causal proof of ad impact, not correlation, making it the right tool for budget and channel-level decisions.
| Point | Details |
|---|---|
| Causal proof, not correlation | Incrementality testing isolates true lift by comparing exposed vs holdout groups in a randomized experiment. |
| Feasibility check first | A low total number of conversions is generally insufficient; sample size scales with 1/lift², so small lifts require larger samples. |
| Match design to constraints | Use user-level holdouts for high-volume digital, geo-split tests for cross-channel or offline, and platform-native studies for directional checks only. |
| Report lift with confidence intervals | A null result is an upper bound on lift, not proof of zero effect; always pair estimates with pre-committed decision rules. |
| The Branded Agency approach | The Branded Agency designs and runs incrementality tests as part of a full measurement stack, including MMM calibration and paid media management. |
Why most teams are measuring the wrong thing
The uncomfortable truth about digital advertising measurement is that most teams are optimizing against signals that were never designed to prove causation. Attribution models were built to allocate credit, not to answer the question "would this conversion have happened without our ad?" Those are fundamentally different questions, and conflating them leads to budgets that grow channels rewarding themselves for organic demand.
What makes incrementality testing genuinely powerful isn't the math. It's the discipline of asking a harder question before spending more money. The teams that run these tests consistently tend to find that some of their highest-attributed channels have the lowest incremental lift, and some of their lowest-attributed channels are driving real demand that the model never saw. That gap between attributed performance and causal performance is where budget decisions go wrong.
The practical recommendation: run an annual rotation of causal tests on your top three spend channels. Use the results to recalibrate your MMM and your internal attribution weights. Treat incrementality testing as episodic, not always-on. It's not a dashboard metric. It's a calibration event. Done once a quarter on a rotating channel basis, it gives you a measurement stack that actually reflects reality rather than one that confirms your existing spend allocation.
The Branded Agency can build your measurement stack
Most paid media programs are flying on attribution data that systematically overclaims. The Branded Agency's measurement practice starts where attribution ends: with causal proof. We design and run incrementality tests as part of a full-funnel paid media management engagement, covering experiment design, holdout architecture, MMM calibration, and stakeholder reporting.
A typical starter engagement includes a measurement audit of your current attribution setup, identification of the top channel candidate for a pilot incrementality test, and a four-to-six-week test with a clean deliverable: lift estimate, confidence interval, incremental revenue impact, and a specific budget recommendation. No ambiguity. No "directionally positive" hedging. A decision you can act on.
If you're ready to know what your ad spend is actually doing, talk to our team about a measurement audit.
Useful Sources for Further Reading
These are the primary references behind the guidance in this article, selected for technical depth and practical applicability for North American marketing teams.
- Soku: What Is Incrementality Testing and How to Run One — The clearest published explanation of the 1/lift² sizing rule, with a conversion threshold table. Use this when computing feasibility for any test design.
- Matomo: Incrementality Testing Quick-Start Guide — A privacy-first walkthrough with calculations, useful for teams building measurement infrastructure without relying on platform-native tools.
- Measured: Incrementality vs Attribution vs MMM Decision Tree — The best single resource for understanding which method answers which business question and how to run them in combination.
- Cometly: Understanding Incrementality Testing — Practical overview of causal lift measurement with worked examples; good for sharing with stakeholders who need the concept explained without heavy statistics.
- Harvard Business Review: A New Gold Standard for Digital Ad Measurement — Executive-level framing of why randomized experiments are replacing last-touch attribution as the measurement standard; useful for building internal buy-in.
Recommended
Quincy Samycia
As entrepreneurs, they’ve built and scaled their own ventures from zero to millions. They’ve been in the trenches, navigating the chaos of high-growth phases, making the hard calls, and learning firsthand what actually moves the needle. That’s what makes us different—we don’t just “consult,” we know what it takes because we’ve done it ourselves.
Want to learn more about brand platform?
If you need help with your companies brand strategy and identity, contact us for a free custom quote.
We do great work. And get great results.
+2.3xIncrease in revenue YoY
+126%Increase in repurchase rate YoY

+93%Revenue growth in first 90 days
+144% Increase in attributed revenue


+91%Increase in conversion rate
+46%Increase in AOV
+200%Increase in conversion rate
+688%Increase in attributed revenue